Grounded, Not Guessing: How Retrieval-Augmented AI Answers From Your Own Documents
A generic chatbot answers from the public internet and sometimes makes things up. Retrieval-augmented generation (RAG) first finds the relevant passages in YOUR documents, then writes an answer grounded in them — with citations. That difference is what makes AI usable for real professional work.
Ask a generic AI chatbot a question about your firm and you’ll get a confident answer. The trouble is you can’t tell whether it’s true. It might be drawing on the public internet, on stale training data, or on nothing at all — the phenomenon known as hallucination, where a model states something plausible but wrong.
For casual use, that’s tolerable. For professional work — advising a client, quoting a policy, citing a precedent — it’s a non-starter. You need answers that come from your material and that you can check.
That is exactly what retrieval-augmented generation (RAG) does.
The idea in one paragraph
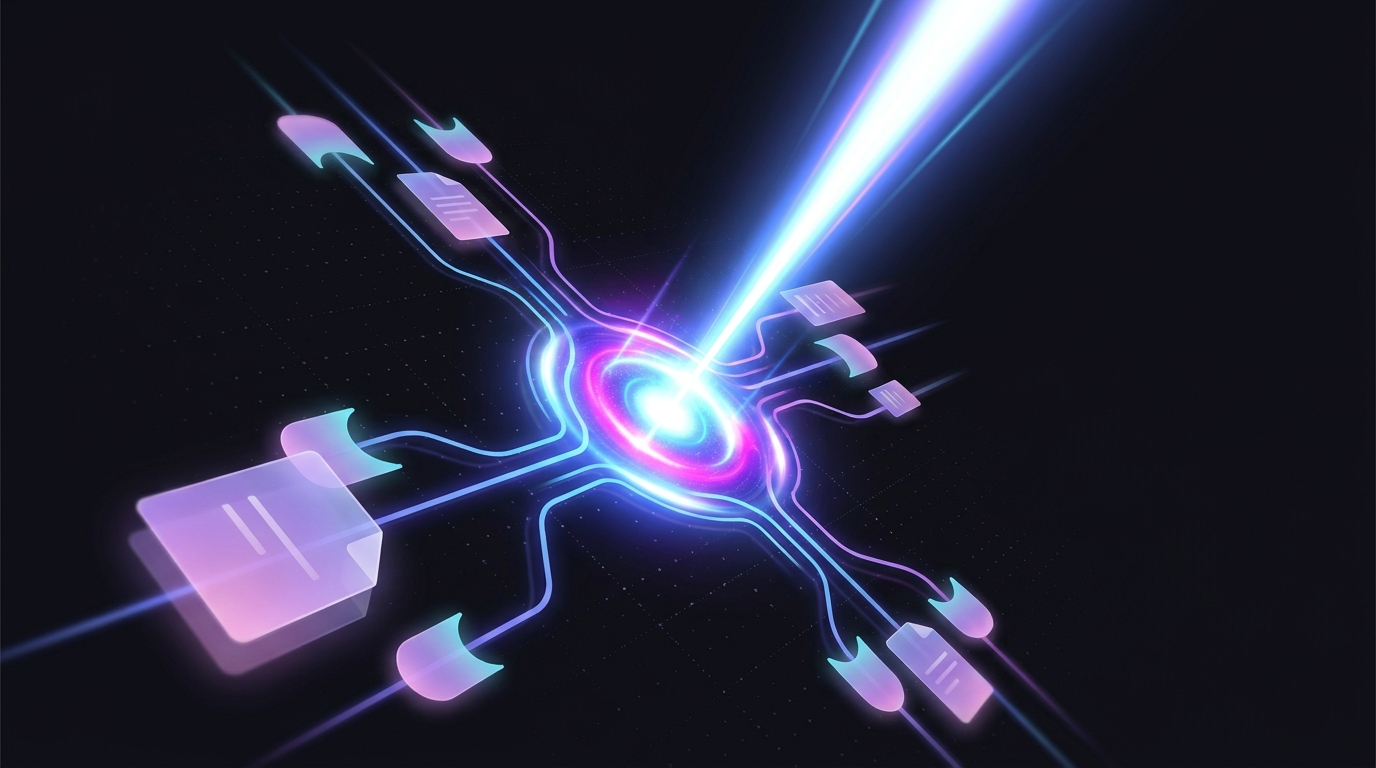
RAG splits the job in two. First, a retrieval step searches a defined set of documents — your documents — and pulls out the passages most relevant to the question. Then a generation step hands those passages to a language model and asks it to write an answer based on them, with the sources attached. The model isn’t answering from memory; it’s answering from evidence you provided.
The technique was formalised in a 2020 paper, Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks, and has since become the standard way to make AI reliable for business use. Google Cloud has a good primer if you want the vendor-neutral version.
The shift is subtle but total: from “what does the model think?” to “what do our documents say?”
Why this matters for a knowledge-intensive firm
The problems we’ve written about in this series — knowledge that walks out the door, consultants re-solving solved problems — all come down to one thing: the firm’s knowledge exists in documents nobody can efficiently query. RAG turns that pile of documents into something you can ask.
A few properties make it the right fit:
- Grounded and citable. Every answer points back to the source document, so a person can verify it. Trust comes from traceability.
- Always current. Because retrieval happens at query time, updating a document updates the answers. There’s no model to retrain.
- Private by design. Your documents are used to answer, not to train a shared model. Your knowledge stays yours.
How Docent uses it
Inside Docent, the pipeline is straightforward: your documents are broken into passages and converted into mathematical representations (embeddings) stored in a per-tenant index. When someone asks a question, Docent finds the closest-matching passages from your firm’s content and grounds the answer in them, with the source attached. Nothing from another company’s tenant is ever in scope.
Two things make this safe for European firms specifically. The whole pipeline — embeddings, retrieval, generation — runs inside the EU, which we cover in Where Your Data Lives Matters. And the same grounded knowledge base can be transformed into onboarding paths, briefings, and study guides, which we explain in From Document to Podcast, Quiz & Briefing.
What RAG doesn’t do
It’s worth being honest about the boundaries. RAG makes answers grounded, not infallible — retrieval can miss a relevant document, and a model can still misread a passage. The right posture is “trusted assistant, verifiable source,” not “oracle.” That’s why Docent always shows the source: the human stays in the loop, but starts from the firm’s real knowledge instead of a blank page.
The takeaway
The difference between a chatbot and a professional tool is grounding. RAG is what turns “an AI that talks” into “an AI that answers from your firm’s own knowledge, with receipts.” For firms whose credibility depends on being right, that’s the whole game.
More on how we keep it EU-native in Where Your Data Lives Matters. Follow Docent on LinkedIn.
Frequently asked questions
What is retrieval-augmented generation (RAG)?
RAG is an AI technique that first retrieves relevant passages from a specific set of documents, then uses a language model to write an answer based on those passages. It grounds the answer in real source material instead of relying only on what the model learned during training. The approach was introduced in a 2020 research paper by Lewis et al.
How is RAG different from a normal chatbot?
A normal chatbot answers from its general training data and can 'hallucinate' — state something plausible but wrong. A RAG system answers from a defined, trusted document set and can cite the exact source, so answers are traceable and firm-specific.
Does Docent train an AI model on my documents?
No. Docent retrieves from your documents at query time to ground each answer; your content is not used to train a shared model. This keeps your knowledge private and your answers current whenever documents change.
See what your firm already knows.
Docent turns your documents into a queryable, teachable institutional memory — EU-native and GDPR-first.